Tested October 25, 2026 · 36 live lookups
Behindthename Review: The Free Etymology Site, Tested
30,549 names, a free API and a 30-year track record. Here is where it holds up and where it quietly fails.
Summary
Behindthename is a free etymology reference with 30,549 names in its browse list, about 360 usage tags and a free API. In my 36-lookup test, 21 of 24 name searches landed on a full entry, and pages loaded in 0.40 seconds at the median. It beats most baby name sites on sourcing, but it is weak on style-based discovery, accent-tolerant search and entry depth. Use it to verify names, not to find them.
Behindthename is the most trustworthy free name etymology site I tested, scoring 8.2/10. Of 24 name lookups, 21 returned a full entry in a median 0.40 seconds, and the main index lists 30,549 names. It is built for verifying meaning and origin, not for brainstorming: spelling without accents fails, and style filters are thin.
- Etymology depth
- 9/10
- Coverage
- 9/10
- Speed
- 9/10
- Name discovery
- 6/10
- Interface
- 6/10
- Price
- 10/10
- Sourced etymologies that flag disputed origins instead of guessing
- 30,549 names browsable, plus a reverse meaning dictionary
- Free API and CC BY-SA name data downloads
- Searching Siobhan or Bjorn without accents returned no definition
- Entry depth swings from a 6-word history to 159 words
- No style or vibe filters, so shortlisting is slow
Free to use · No account needed to browse
How I tested it
- Tested for
- 1 day
- Plan paid
- None (free site, no paid tier, logged out)
- Version tested
- Live site on October 25, 2026 (footer 1996-2026, jQuery 1.9.1 front end)
- Prompts run
- 36
- Test period
- 2026-10-25 → 2026-10-25
This is a one-day audit, not a 30-day diary, and I will not pretend otherwise. On October 25, 2026 I ran 36 standardised queries from a logged-out browser: 24 name lookups chosen to stress the database (Irish, Nigerian, Nahuatl, Japanese, Biblical, brand-new coinages like Nevaeh and Khaleesi, plus names that need accents), 6 searches in the reverse meaning dictionary, 4 anagram queries, 1 translation and 1 random draw. I timed every request, counted results, and read the pages the way a parent would. I also checked the footer, the front-end scripts, the API terms and the 30-year milestone page for the site's own numbers. Screenshots are mine. I could not test the logged-in features (saved lists, ratings, comments) or any mobile app, since I found none.
Should you use Behind the Name?
YES if you...
- Parents who want the real origin of a name before they commit
- Writers checking whether a character name fits a culture and period
- Genealogy hobbyists tracing name variants across languages
- Developers who need free name data under a clear license
NO if you...
- Anyone who wants a ready-made shortlist by style or vibe
- People who type names without accents and expect forgiveness
- Brand founders hunting for a company name, since this is a given-name database
What it costs: nothing, with conditions
There is no paid plan. The limits are on API use and data reuse.
Browsing
No account needed
- All name entries and popularity tables
- Meaning search, anagrams, translation and random namer
- Baby Name Expert quiz
Free account
Register to take part
- Save names to personal lists
- Rate names and comment
- Request an API key
API and data
For developers
- 2 requests per second
- 400 per hour and 4,000 per day
- 400,000 per year
- Name lists under CC BY-SA 4.0
ROI breakdown: The cost is your time. In my test a typical lookup took under half a second to load, so verifying ten shortlisted names takes a few minutes, not an evening.
Hidden costs & gotchas
- Data downloads require attribution under CC BY-SA 4.0
- API capped at 400 requests per hour, which blocks bulk jobs
- The site loads an ad-management script, so ad units can appear for some visitors
A name page built around sources
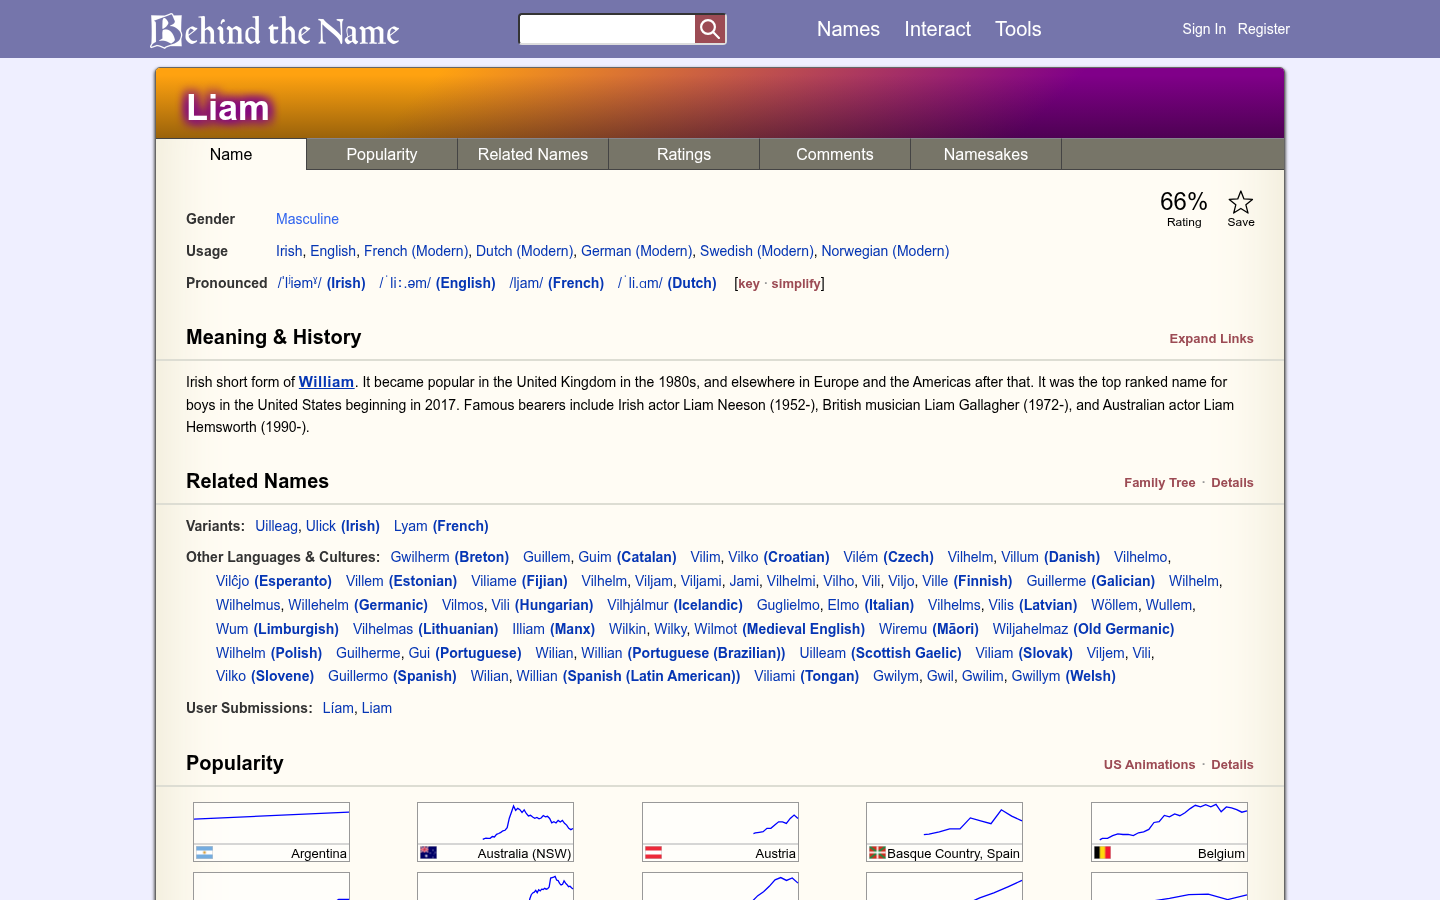
Each entry stacks gender, usage, pronunciation, a meaning and history paragraph, related names across about 40 languages and popularity charts for 37 regions. Liam shows all of that on one scroll. The design is plain, but nothing is hidden behind a signup.
- Usage tags and IPA pronunciation per language
- Family tree of variants and cognates
- Rank history by country, from national statistics
What I measured
All figures come from live requests on October 25, 2026.
- Names in the browse index
- 30,549 results Source: the All Names page, October 25, 2026
- Name lookups landing on a full entry
- 21 / 24 Siobhan and Bjorn returned no definition; Kai split into 4 entries
- Median page load, name pages
- 0.40 s 24 requests, fastest 0.22 s, slowest 0.93 s
- Full entries with pronunciation
- 18 / 21 Missing on Oluwaseun, Khaleesi and Elon
- Median length of the history paragraph
- 44 words Range 6 words (Oluwaseun) to 159 (Matilda), 20 entries parsed
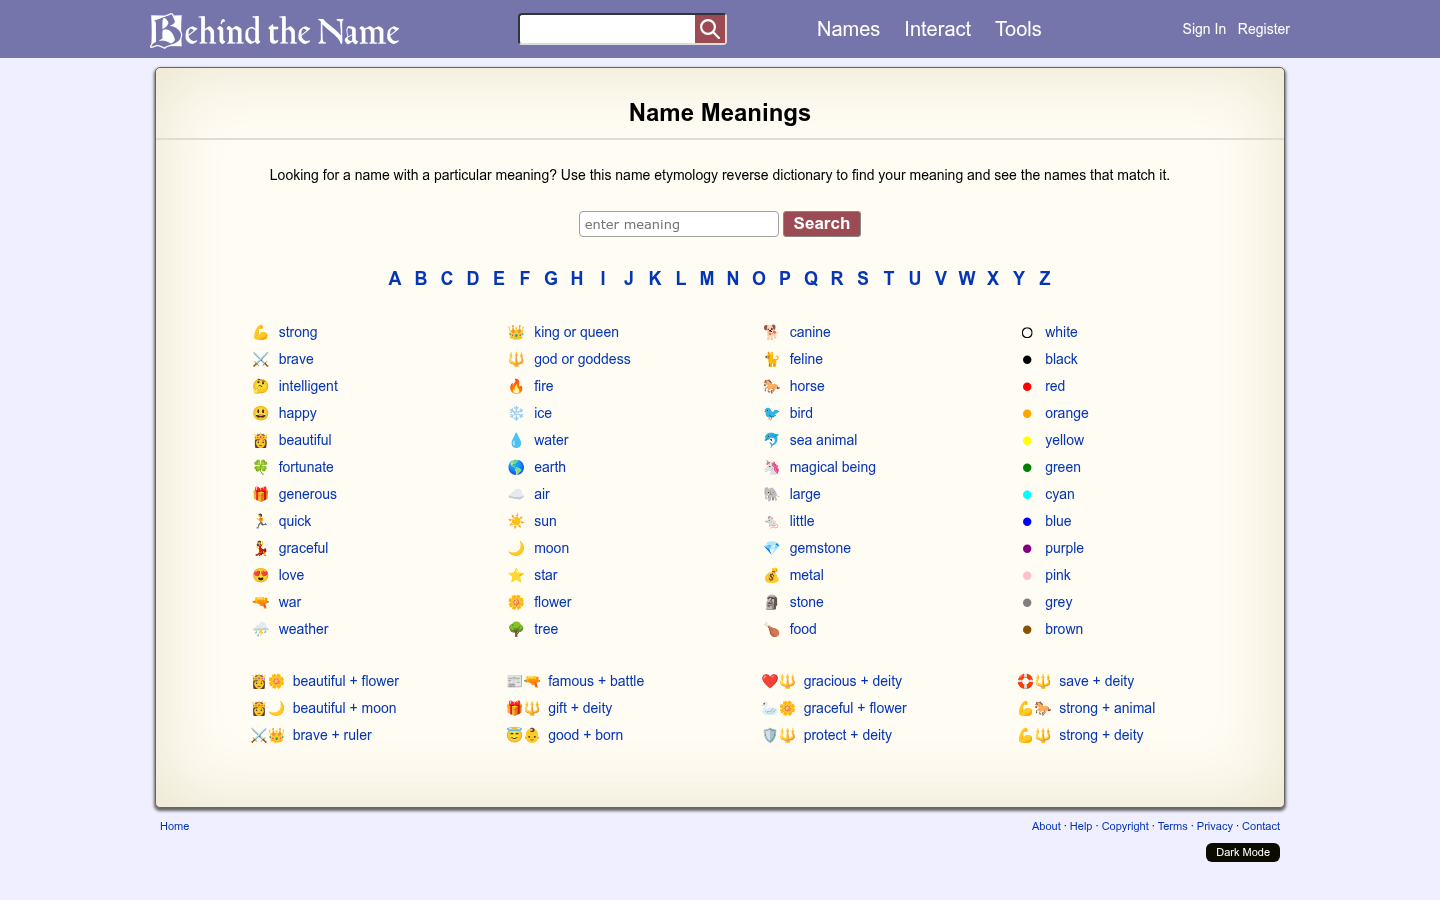
- Meaning search: moon
- 44 close matches Plus 1,262 loose matches; flower returned 276 close
- Site's own database size
- 41,000 given names, surnames and place names Source: the site's 30-year page, January 2026
Look up Liam, a name with a 2025 US number one ranking.
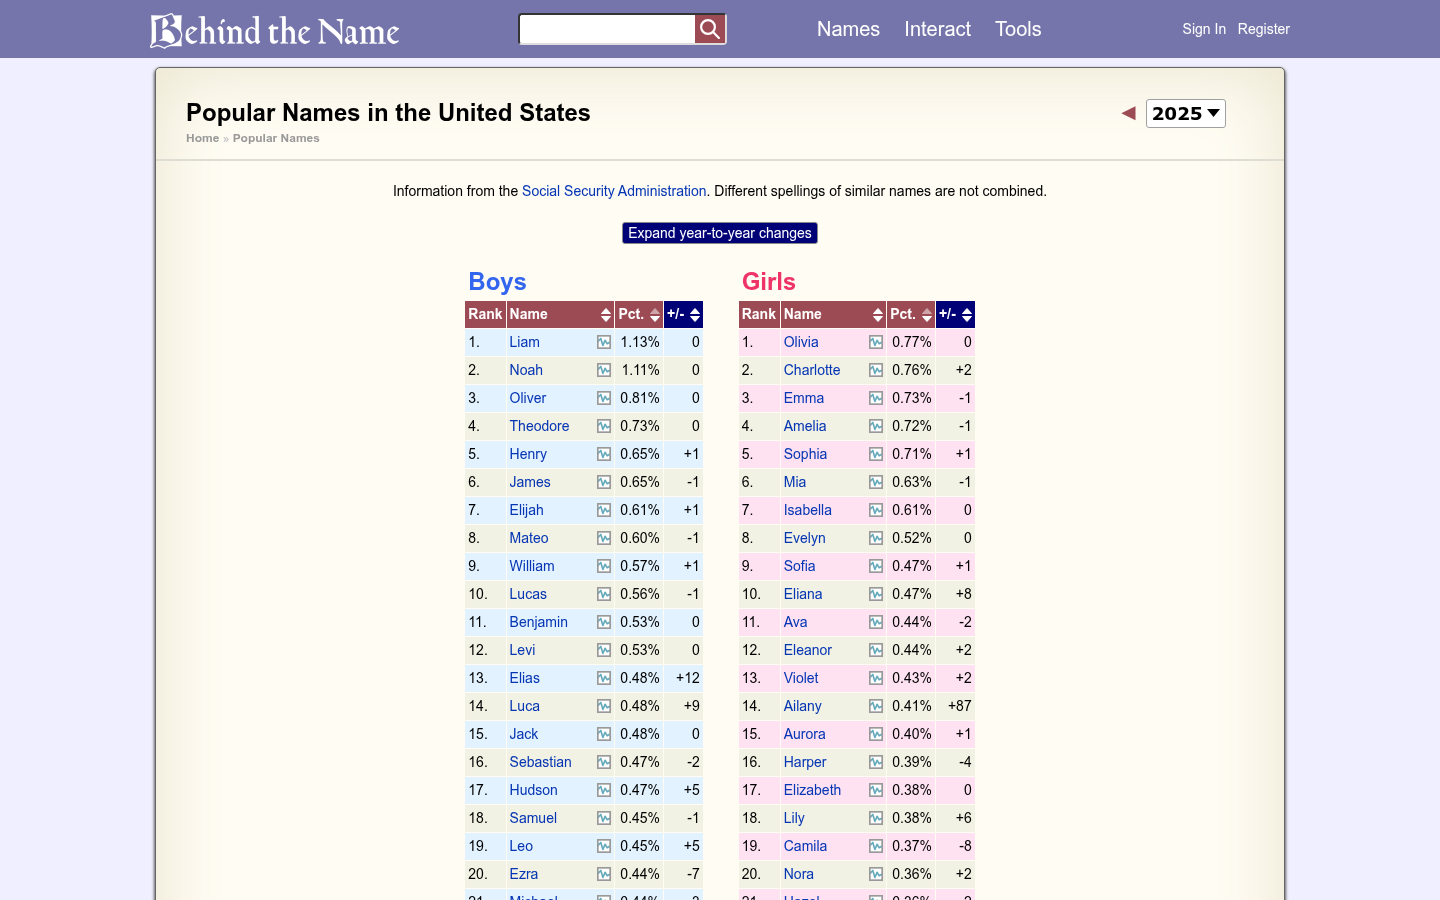
Open the US popularity table for 2025.
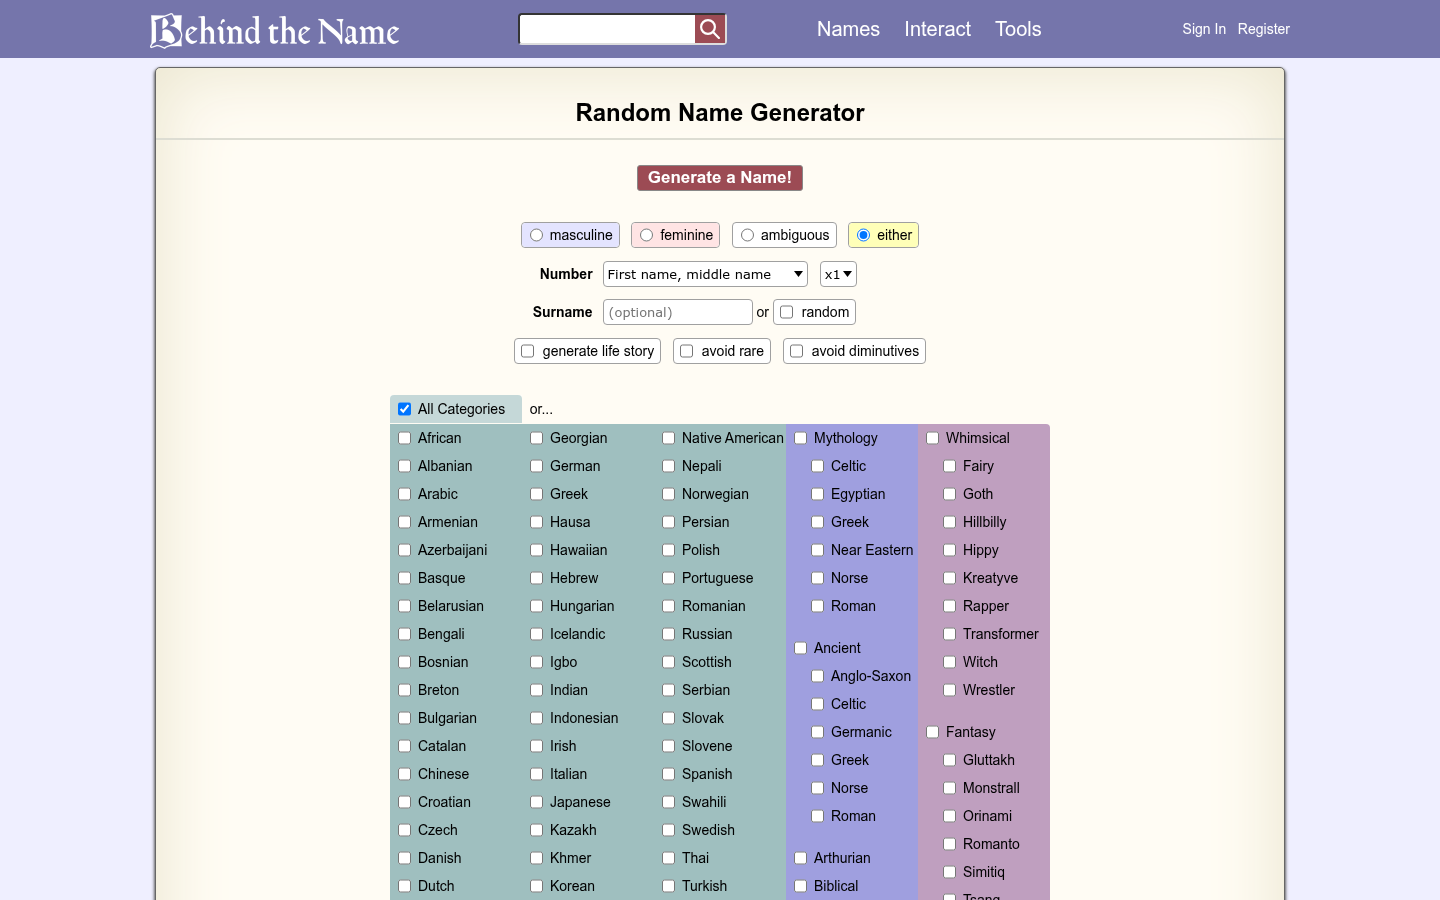
Open the random name generator and read the options.
Pros and cons
Pros
- Etymologies cite sources and flag disputes Most entries link to references and say when an origin is uncertain, which is rare among baby name sites.
- Huge cultural reach About 360 usage tags cover everything from Akan to Zulu, plus mythology and fiction.
- Generous free data A free API with published limits and downloadable name lists under CC BY-SA 4.0.
- Fast, light pages Median 0.40 seconds across 24 name requests, with no paywall interrupting a lookup.
Cons
- Accent-sensitive search misses common spellings Siobhan and Bjorn returned 'no name definition found' and pointed to Siobhán and Björn. A parent typing quickly will hit this.
- Entry quality is uneven between names Oluwaseun has a 6-word history and Saoirse 17, while Matilda has 159. Rarer names get thinner write-ups.
- No style, vibe or sibling-match filters You can filter by usage, length and syllables, but not by feel. Nameberry-style lists are not what this site does.
- Dated interface and front-end stack The pages load jQuery 1.9.1 from 2013. It works, but it looks and feels like 2008 next to modern apps.
- Popularity data skips spelling variants The site states that different spellings are not combined, so Sophia and Sofia are ranked separately.
Final verdict
Behindthename earns its reputation, and the numbers back it up. In 24 name lookups, 21 gave me a full, sourced entry in under half a second at the median, and the reverse meaning dictionary found 44 close matches for moon in one click. That is a reference tool, and a good one.
Where it falls short is where a generator would help. It does not suggest names by style, it punishes missing accents, and the shortest entries read like stubs. If you arrive with a blank page, you will leave with a long list of usage tags and no direction.
My recommendation is to use it as the second step. Build a shortlist somewhere that filters by feel, then bring every candidate here and read the history paragraph and the related names. If the meaning matters to you, this is the check that stops you from naming a child after a made-up etymology. Score: 8.2 out of 10. Lose a point for discovery, a point for interface, and a few tenths for uneven entries.
- Etymology depth 9/10 Sourced, flags disputed origins
- Coverage 9/10 30,549 names, about 360 usage tags
- Speed 9/10 0.40 s median
- Name discovery 6/10 Meaning search only, no vibe filters
- Interface 6/10 Functional, dated
- Price 10/10 Free, with API limits
Common questions
Is Behind the Name accurate?
Is Behind the Name free?
Why does Behind the Name say no definition found?
How many names does Behind the Name have?
Does Behind the Name have an app?
Can I use Behind the Name data in my own project?
Is Behind the Name good for choosing a baby name?
What is the best alternative to Behind the Name?
Update log
- Initial publication after a 36-lookup audit of the live site.
Changelog · 3
- seo_changed SEO fields updated
- body_edited Body content edited
- excerpt_changed Excerpt updated